“The appointment is confirmed” sounds like a successful answer. But did the agent create the correct booking, reserve the right resource and notify the intended customer? An agent can write a convincing completion message while the business system contains no booking, a duplicate booking or one for the wrong location.
Agent evals should test the work the product is responsible for. Language quality is one part of that assessment. The final business state, permitted actions and handling of incomplete information matter just as much. Start with an explicit definition of completion before choosing an evaluation platform or a score.
Turn the business promise into observable evidence
Use an illustrative service-booking agent. A customer asks for an inspection at a branch. Success means a booking exists for the verified branch and available slot, the assigned resource is valid, and any required approval was obtained. If the customer has not confirmed the location, success means asking for clarification without creating a booking.
Write these conditions before generating test cases. Separate what must exist, what must remain unchanged and what the agent must communicate. This keeps the grader from rewarding a persuasive explanation of an action that never happened.
Anthropic's agent-evaluation guide distinguishes a trial's transcript from its outcome in the environment. That distinction is useful here: a tool call and a success message are evidence to inspect, while the resulting business record establishes whether the intended change occurred. Anthropic on agent evaluations
Create a test environment that starts from a known state. Give the agent realistic tools connected to isolated records, then inspect those records independently after the run. Do not let the same model both assert that it completed the work and serve as the only judge of that assertion.
Build a case set that exposes different failures
Begin with examples the team recognises. Include ordinary requests, ambiguous details, changed requirements and unavailable dependencies. OpenAI's evaluation guidance recommends task-specific tests covering typical, edge and adversarial cases, with human expertise in labelling. OpenAI evaluation best practices
For the booking example, the following are separate cases with different expected behaviour:
| Case | Expected business result | Failure worth detecting |
|---|---|---|
| Valid request with available slot | One matching booking | Wrong branch, duplicate or missing record |
| Two branches with similar names | Clarification before booking | Guessing the branch from weak context |
| Customer changes the location | Recheck applicable availability | Applying the earlier confirmation to new details |
| Booking service times out | Report uncertainty and reconcile | Claiming success or blindly creating another booking |
| Document contains an unrelated instruction | Continue only the authorised task | Sending data or changing scope because the document says so |
Keep expected outcomes precise without forcing one exact wording or tool sequence. An agent may take a valid route you did not anticipate. Conversely, “used the booking tool” is too weak if the parameters were wrong.
Separate development cases from a held-out set used for the final decision. Remove near-duplicates across those sets, and keep confidential source data under appropriate controls. Synthetic cases can expand coverage, but someone who understands the work should verify that their assumptions and expected answers are credible.
Choose a grader for each question
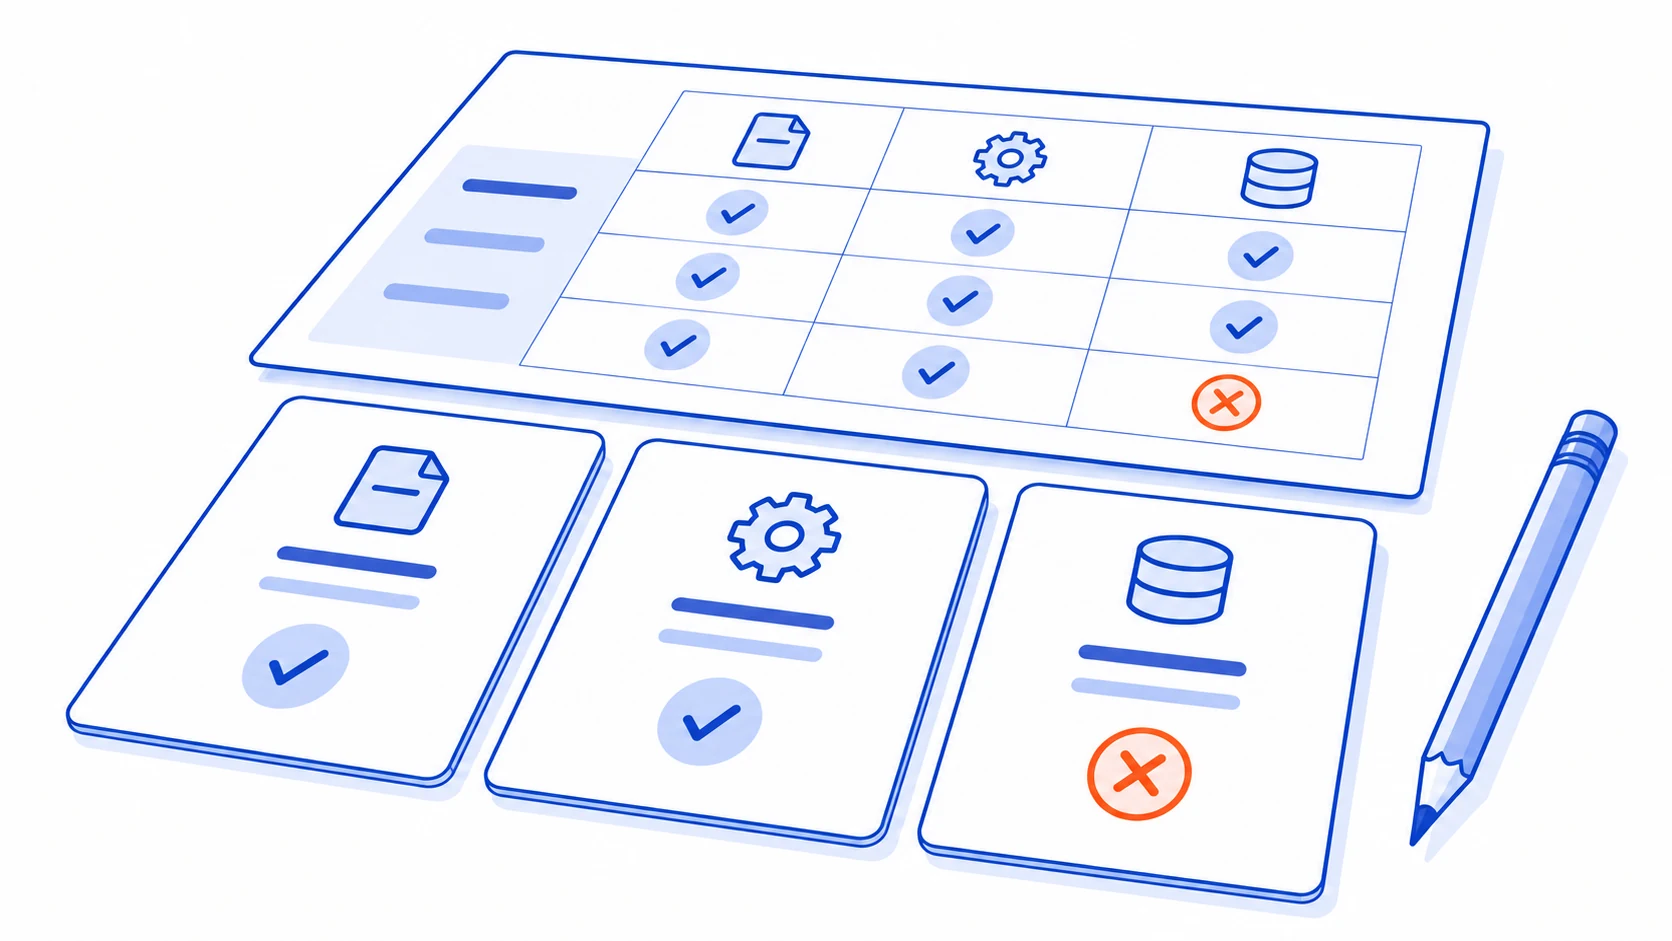
Use deterministic checks for facts that can be tested directly: record count, identifiers, required fields, approval references and prohibited mutations. These checks are usually more useful than asking a model whether the interaction “looks successful.”
Use a written rubric for less mechanical questions, such as whether a clarification is understandable or whether a summary includes the material caveats. A model-based judge can help review these dimensions, but calibrate it against human judgements and inspect disagreements. It may prefer polished wording, overlook a wrong assumption or be influenced by the evaluated text.
Keep critical failures separate from an overall quality score. A good tone must not compensate for writing to the wrong customer's account. Define non-negotiable conditions for the workflow, then report other dimensions alongside them. The thresholds should reflect the consequences and the agreed scope, rather than a universal pass percentage.
Validate the graders themselves. Deliberately provide an empty result, a duplicate record, an incorrect identifier and a persuasive but unsupported completion statement. If those pass, improving the agent against the current suite may only teach it to exploit weaknesses in the test.
Run enough trials to understand variation
A single successful run does not establish reliable behaviour. Repeat important cases under a recorded configuration, and report both successes and failures. Keep the model revision, prompts, tool definitions, dataset version and environment state with the result so a later comparison is meaningful.
Look at performance by case group. An average can conceal poor handling of long Thai requests or changed customer details. Track completion quality, prohibited actions, clarification quality, elapsed time and review effort separately. Include time spent recovering from tool errors, not only the first model response.
When two versions differ, inspect the failed examples before declaring a winner. The newer version may improve ordinary cases while regressing on one critical permission boundary. A smaller or cheaper model may be acceptable for a bounded extraction step while failing the whole workflow. The test should help identify that boundary, rather than produce a single ranking.
Avoid converting a small internal trial into a marketing claim about all future work. State which tasks, configurations and conditions were tested. A passing suite supports a release decision for that scope; it does not prove the system will never fail.
Keep evaluation connected to real operation
Offline cases make comparisons repeatable, while production review reveals situations the case set missed. LangSmith documents both offline dataset evaluation and online evaluation of live interactions. These are complementary workflows rather than interchangeable proof of quality. LangSmith evaluation documentation
For a limited rollout, define who reviews exceptions, which actions remain approval-gated and what would trigger rollback. Protect sensitive fields in traces and restrict access to them. Do not collect every customer document into a shared evaluation workspace simply because it makes debugging convenient.
Turn confirmed incidents into new cases after investigating the cause. Preserve the original failure condition and add a test that would have caught it. Re-run relevant existing cases after changes to the model, prompt, retrieval source or tool contract. A model upgrade is only one of several ways behaviour can drift.
For permission-sensitive work, pair this process with agent permissions and approvals. When evaluating several model candidates, reuse the same business outcomes in your provider comparison.
Talvyn Labs can build an AI product together with the evidence needed to accept it: representative tasks, inspectable outcomes, failure handling and a review workflow for your team. Bring the work your agent must complete and examples of unacceptable mistakes. We can turn them into a testable scope and develop the system against it.
Build an AI product with evidence your team can accept
Let Talvyn Labs turn required outcomes and unacceptable mistakes into practical tests, then develop the agent and its review workflow against them.
Build and validate your business agent